Research · Foundation models & agents研究 · 基础模型与智能体

Xu Chu褚旭

Algorithm Engineer · Xiaohongshu Pevek算法工程师 · 小红书 Pevek 基础模型团队

I currently work at Xiaohongshu’s Pevek Foundation Model Team, researching post-training and reinforcement learning for foundation models, with a focus on Search Agents and Cowork Agents. My current interests include building automated environment synthesis frameworks that produce environments with human-expert-level quality, improving agents’ ability to execute long-horizon tasks in complex environments, and improving models’ effectiveness across real-world search scenarios.

I received my M.S. in Software Engineering from Peking University, advised by Prof. Weiping Li. During my graduate studies, my research focused on improving the reasoning capabilities of LLMs and VLMs. I published eight papers at top-tier conferences as first or co-first author, including ACL, CVPR, and WWW.

我目前就职于小红书 Pevek 基础模型团队,主要研究基础模型的后训练与强化学习,重点关注 Search Agent 与 Cowork Agent。我目前主要关注:构建具备人类专家级质量的自动化环境合成框架,提升 Agent 在复杂环境中执行长程任务的能力,提升模型在各种真实搜索场景中的应用效果。

我硕士毕业于北京大学软件工程专业,师从李伟平教授。在研究生期间,我的研究方向是提升LLM和VLM的推理能力。我以第一作者/共同一作发表了8篇顶会文章,包括ACL、CVPR、WWW等。

Xu Chu
Beijing, China中国 · 北京
chuxu@alumni.pku.edu.cn

News近期动态

01

Selected publications精选论文

02

* Equal contribution.* 表示共同贡献

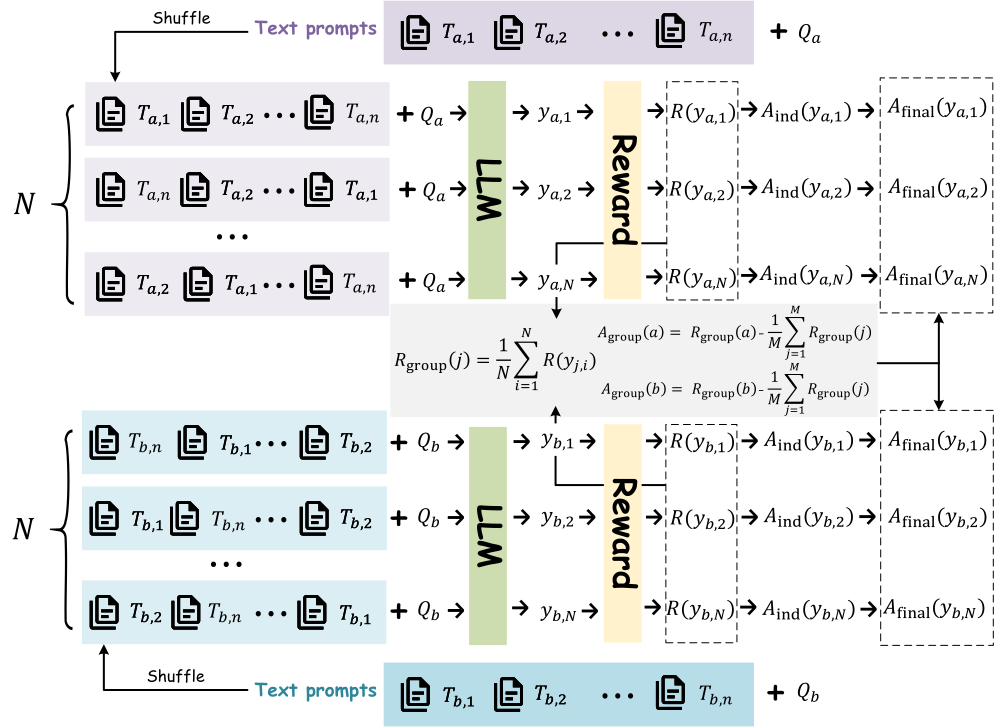
dgao — method overview from the paper / 论文方法概览
Original paper figure论文原图
ACL 2026Reinforcement learning强化学习

Towards Order Fairness: Mitigating LLMs Order Sensitivity through Dual Group Advantage Optimization迈向顺序公平:通过双组优势优化缓解大语言模型的顺序敏感性

Xu Chu, Guanyu Wang, Zhijie Tan, Xinrong Chen, Ziyu Li, Tong Mo, Weiping Li

The same evidence in a different order can change an LLM’s answer. DGAO combines within-group accuracy advantages with between-group stability advantages, training models to be both correct and consistent across input permutations.大模型对输入顺序的敏感性是序列建模架构固有的局限性之一:输入同样的证据,仅仅调整排列顺序就可能改变模型答案。DGAO 将组内准确性优势与组间稳定性优势结合,通过强化学习同时提升回答的正确性和对输入顺序的稳定性。

英文原题

Towards Order Fairness: Mitigating LLMs Order Sensitivity through Dual Group Advantage Optimization

rado — method overview from the paper / 论文方法概览
Original paper figure论文原图
ACL 2026Reliable reasoning可靠推理

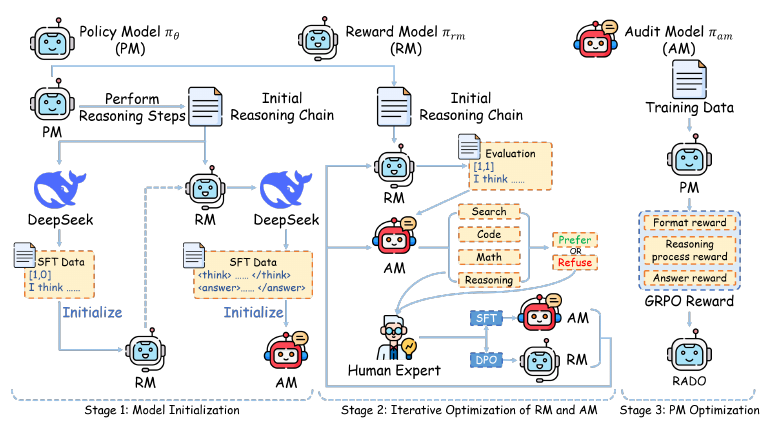
RADO: Reasoning Audit-Driven Optimization for Rigorous Reasoning in High-Stakes DomainsRADO:以推理审计驱动优化,提升高风险领域的推理严谨性

Zhijie Tan*, Xu Chu*, Guanyu Wang, Ziyu Li, Weiping Li, Tong Mo

A correct final answer can conceal flawed reasoning. RADO uses a tool-augmented audit model to locate logical errors, refine a reward model through preference optimization, and guide policy training with rewards for both reasoning and answers.最终答案正确,并不代表推理过程严谨。RADO 利用可调用外部工具的审计模型定位逻辑错误,通过偏好优化改进奖励模型,再以兼顾推理过程与最终答案的奖励指导策略训练。

英文原题

RADO: Reasoning Audit-Driven Optimization for Rigorous Reasoning in High-Stakes Domains

muse — method overview from the paper / 论文方法概览
Original paper figure论文原图
ACL 2026Graph reasoning图推理

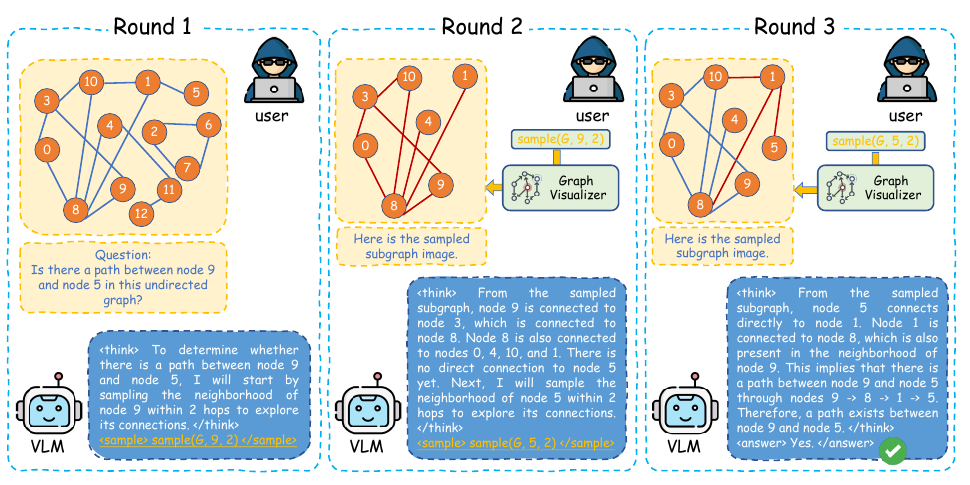
MuSe: Multi-Stage Graph Reasoning via Vision-Language ModelsMuSe:基于视觉语言模型的多阶段图推理

Guanyu Wang*, Xu Chu*, Zhijie Tan, Xinrong Chen, Tong Mo, Weiping Li

Large graph images are cluttered and hard to reason over. MuSe alternates reasoning with targeted subgraph sampling and visualization, progressively gathering the evidence needed for an answer; SFT and reinforcement learning teach the model how to explore.大型图(Graph)中的边和节点容易存在堆叠和遮挡,妨碍图推理。MuSe 交替进行推理、任务相关子图采样与可视化,逐步收集回答所需的信息,并通过监督微调和强化学习优化探索策略。

英文原题

MuSe: Multi-Stage Graph Reasoning via Vision-Language Models

picque — method overview from the paper / 论文方法概览
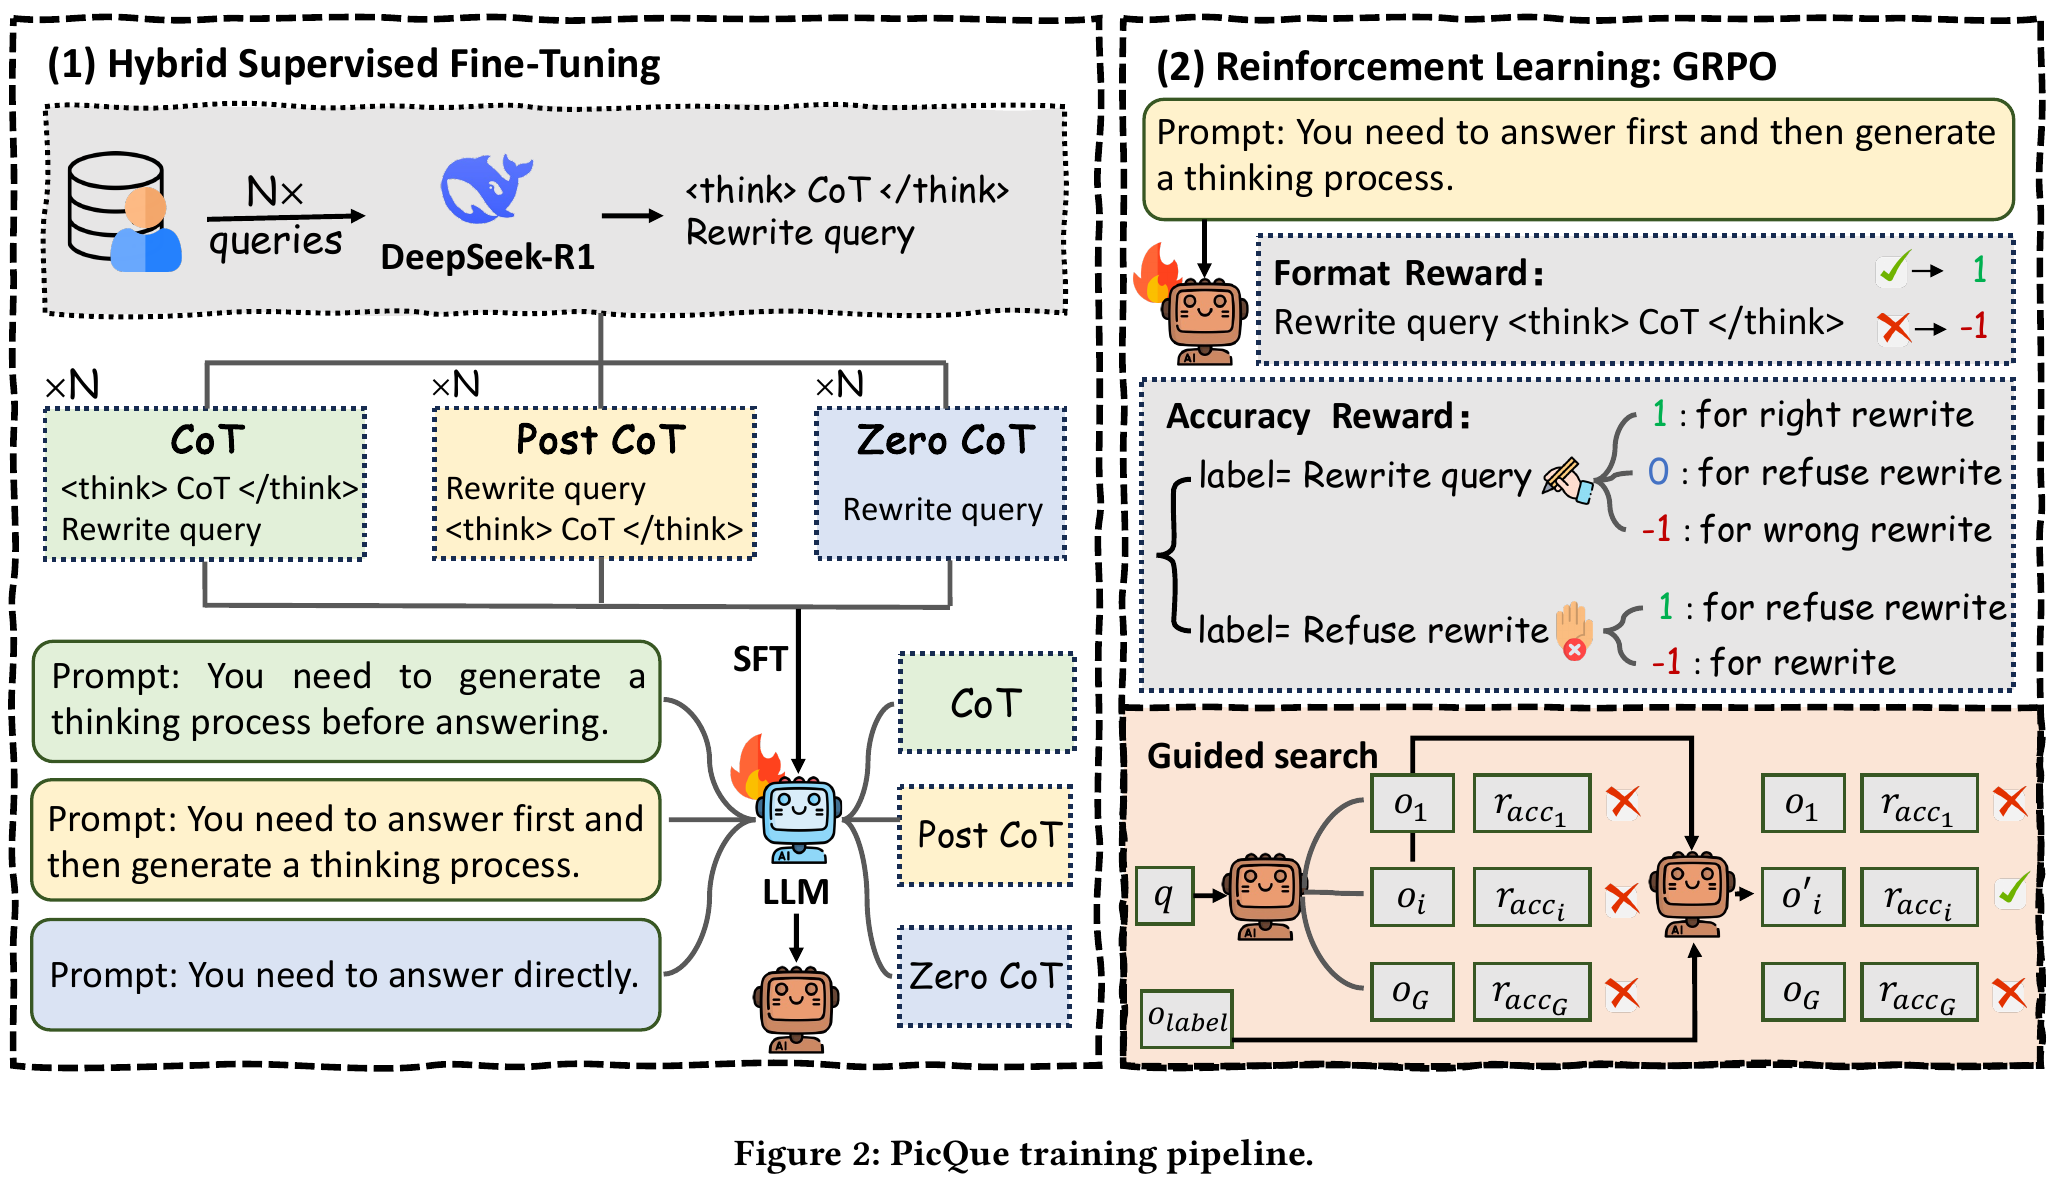
Original paper figure · Figure 2论文原图 · 图 2
WWW 2026Efficient search高效搜索

Accurate and Efficient Personalized Query Rewriting in Baidu Search百度搜索中准确且高效的个性化查询改写

Xu Chu, Angela Li, Jiaming Zhang, Wei Li, Zhijie Tan, Dawei Yin, Shuaiqiang Wang, Daiting Shi

Personalized rewriting needs to infer user intent without slowing search. PicQue combines hybrid supervised fine-tuning with GRPO and guided search, retaining the benefits of reasoning while enabling short, direct query rewrites at inference time.个性化查询改写需要理解用户意图,同时满足在线搜索的低延迟要求。PicQue 将混合监督微调与 GRPO、引导搜索结合,保留推理带来的收益,同时在推理阶段直接生成简短的查询改写。

英文原题

Accurate and Efficient Personalized Query Rewriting in Baidu Search

resdec — method overview from the paper / 论文方法概览
Original paper figure论文原图
CVPR 2026Vision & language视觉与语言

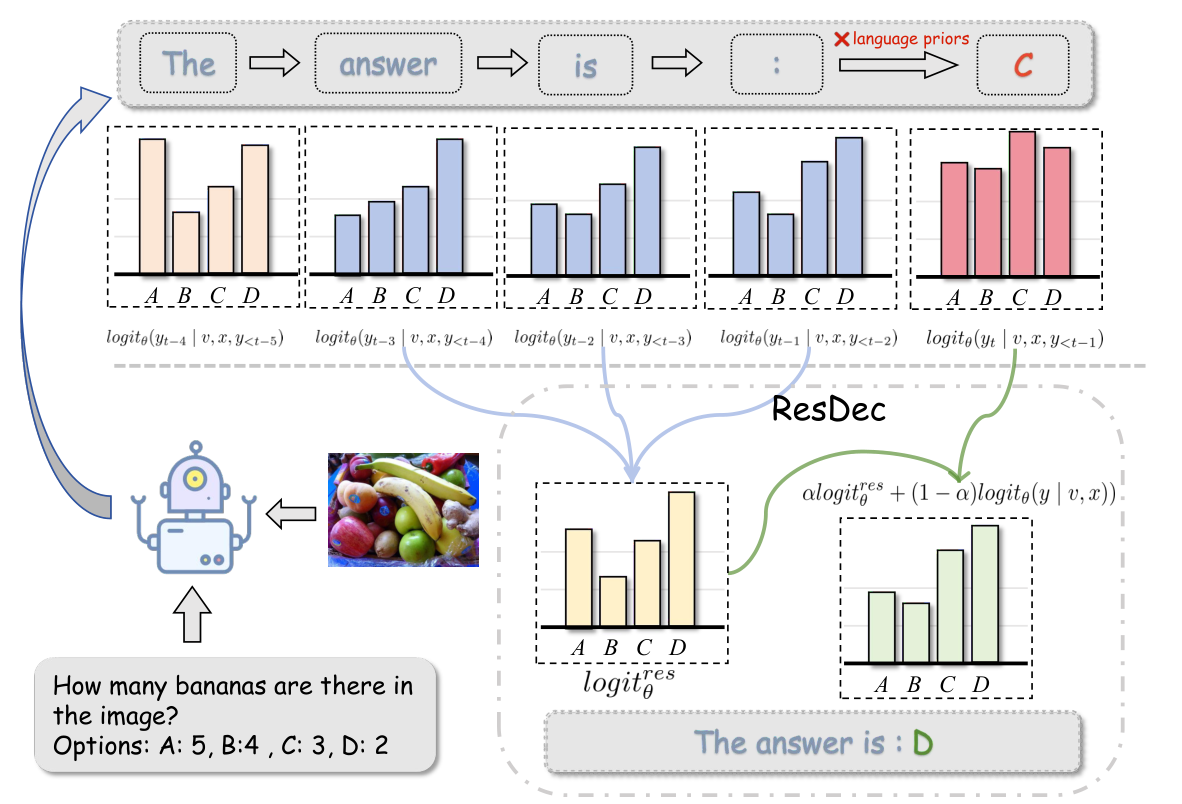
Residual Decoding: Mitigating Hallucinations in Large Vision-Language Models via History-Aware Residual Guidance残差解码:通过历史感知残差引导缓解大型视觉语言模型的幻觉

Xinrong Chen*, Xu Chu*, Yingmin Qiu, Hengyuan Zhang, Jing Xiong, Shiyu Tang, Shuai Liu, Shaokang Yang, Cheng Yang, Hayden Kwok-Hay So, Ngai Wong

During generation, language priors can pull a vision-language model away from image evidence. Residual Decoding aggregates historical token distributions with confidence weights and uses the resulting residual signal to guide the next token, without additional training.生成过程中,语言先验可能使视觉语言模型偏离图像事实。残差解码以置信度加权聚合历史词元分布,再用历史残差信号引导下一词元的选择,无需额外训练。

英文原题

Residual Decoding: Mitigating Hallucinations in Large Vision-Language Models via History-Aware Residual Guidance

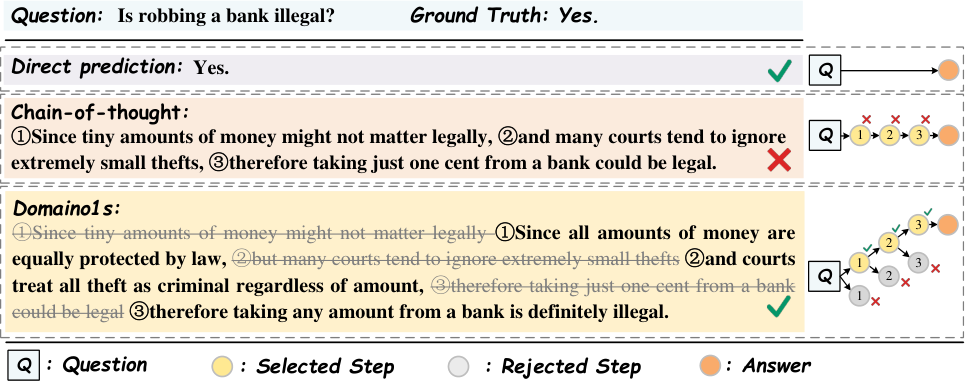
domaino1s — method overview from the paper / 论文方法概览
Original paper figure论文原图
ACL 2025Reliable reasoning可靠推理

Domaino1s: Guiding LLM Reasoning for Explainable Answers in High-Stakes DomainsDomaino1s:引导大语言模型在高风险领域给出可解释答案

Xu Chu*, Zhijie Tan*, Hanlin Xue, Guanyu Wang, Tong Mo, Weiping Li

High-stakes questions need explanations that can be examined. Domaino1s combines domain-specific reasoning fine-tuning with Selective Tree Exploration to search promising reasoning paths, and introduces PROOF-Score to evaluate the quality of the explanations.高风险领域的问题需要可供审查的解释。Domaino1s 结合领域推理微调与选择性树探索,搜索更优的推理路径,并提出 PROOF-Score,从推理完整性、领域安全性和事实准确性评估解释质量。

英文原题

Domaino1s: Guiding LLM Reasoning for Explainable Answers in High-Stakes Domains

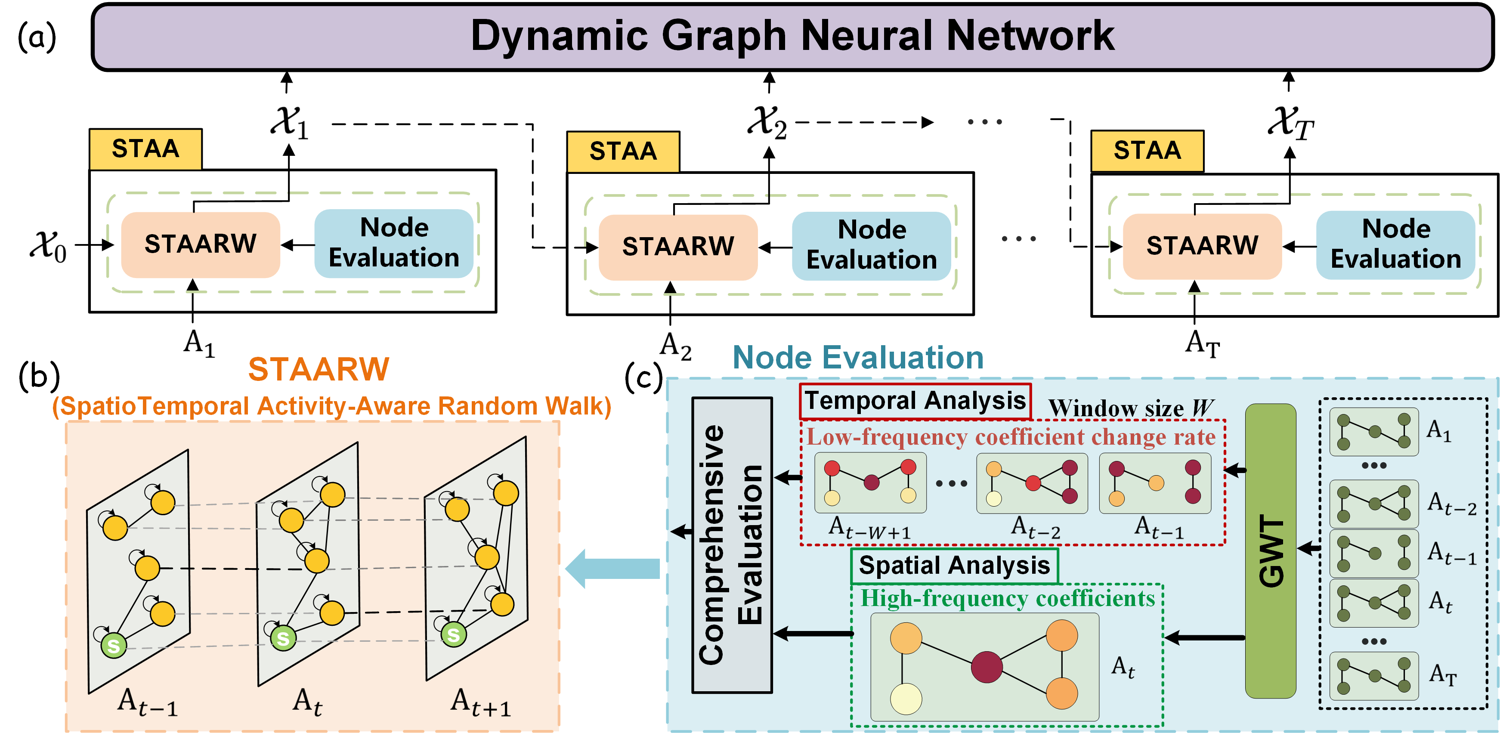
staa — method overview from the paper / 论文方法概览
Original paper figure论文原图
ICASSP 2025Dynamic graphs动态图学习

Adaptive Spatiotemporal Augmentation for Improving Dynamic Graph Learning用于改进动态图学习的自适应时空增强

Xu Chu*, Hanlin Xue*, Bingce Wang, Xiaoyang Liu, Weiping Li, Tong Mo, Tuoyu Feng, Zhijie Tan

Recent edges in a dynamic graph may be noise rather than useful signals. STAA uses graph wavelets to identify noisy spatiotemporal changes, then applies random-walk diffusion to reduce their influence and improve graph learning.动态图中新出现的边未必更有价值,也可能只是噪声。STAA 通过图小波识别时空变化中的噪声,再利用随机游走扩散降低噪声边的影响,为动态图学习构造更可靠的增强结构。

英文原题

Adaptive Spatiotemporal Augmentation for Improving Dynamic Graph Learning

Preprints预印本

03
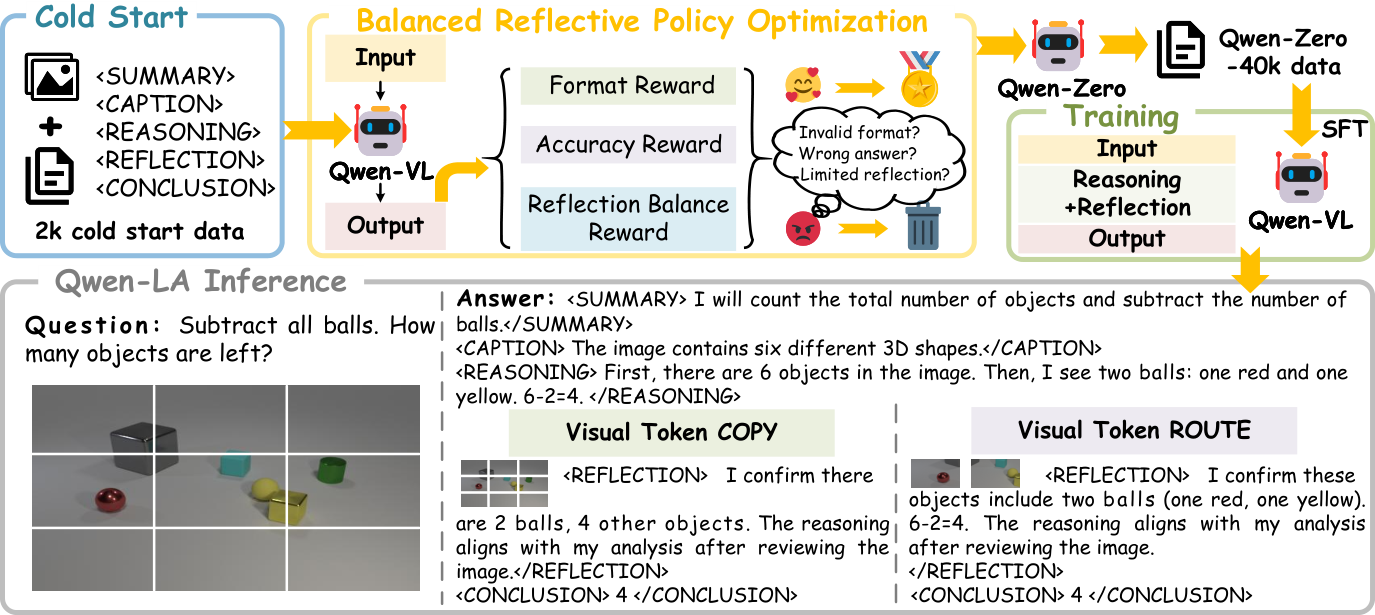
qwen-la — method overview from the paper / 论文方法概览
Original paper figure论文原图
Preprint预印本 2025Visual reasoning视觉推理

Qwen Look Again: Guiding Vision-Language Reasoning Models to Re-attention Visual InformationQwen Look Again:引导视觉语言推理模型重新关注视觉信息

Xu Chu*, Xinrong Chen*, Guanyu Wang*, Zhijie Tan, Kui Huang, Wenyu Lv, Tong Mo, Weiping Li

Longer reasoning can weaken attention to the image. Qwen-LookAgain learns reflective reasoning through BRPO, then uses visual-token copying or routing to reconnect reflection with visual evidence and reduce hallucinations.推理越长,模型对图像的关注越容易变弱。Qwen-LookAgain 通过 BRPO 强化学习算法进行反思式推理,再利用视觉词元复制或路由,让反思过程重新接触视觉证据,从而减少幻觉。

英文原题

Qwen Look Again: Guiding Vision-Language Reasoning Models to Re-attention Visual Information

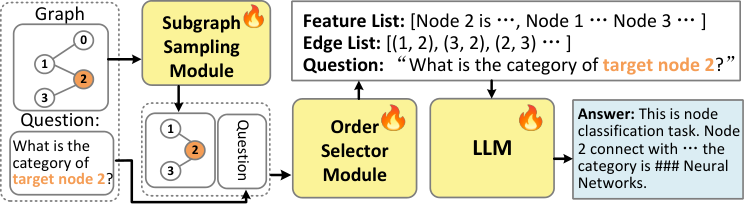
graphsos — method overview from the paper / 论文方法概览
Original paper figure论文原图
Preprint预印本 2025Graph reasoning图推理

GraphSOS: Graph Sampling and Order Selection to Help LLMs Understand Graphs BetterGraphSOS:通过图采样与顺序选择帮助大语言模型理解图

Xu Chu*, Hanlin Xue*, Zhijie Tan, Bingce Wang, Tong Mo, Weiping Li

Turning a graph into text introduces choices about both the neighborhood and its order. GraphSOS learns question-relevant subgraph sampling and sequence selection, then uses graph chain-of-thought distillation to improve structural reasoning.将图转成文本时,采样哪些邻居、如何排列节点与边,都会影响模型表现。GraphSOS 学习与问题相关的子图采样和序列选择,并通过图思维链蒸馏增强模型对结构的理解与推理。

英文原题

GraphSOS: Graph Sampling and Order Selection to Help LLMs Understand Graphs Better

order-matters — method overview from the paper / 论文方法概览
Original paper figure论文原图
Preprint预印本 2024Multimodal robustness多模态鲁棒性

Order Matters: Exploring Order Sensitivity in Multimodal Large Language Models顺序很重要:探索多模态大语言模型的顺序敏感性

Zhijie Tan*, Xu Chu*, Weiping Li, Tong Mo

Can changing the order of images and text change a model’s answer? This study tests text, image, and mixed-modality permutations, revealing substantial sensitivity and limited transfer of good prompt orders across models.只改变图片和文字的排列,是否就会改变模型答案?这项研究系统测试文本、图像和图文混合顺序,揭示多模态模型显著的顺序敏感性,以及优良提示顺序在不同模型之间有限的迁移性。

英文原题

Order Matters: Exploring Order Sensitivity in Multimodal Large Language Models

Experience工作与实习经历

04

2026.04 – Present2026.04 – 至今
Xiaohongshu小红书 ↗ · Pevek Foundation Model Team · Pevek 基础模型团队

Algorithm Engineer算法工程师

Conduct post-training research on foundation models for Search Agent and Cowork Agent applications, continuously enhancing their general-purpose capabilities and effectiveness in real-world business scenarios. Contribute to the development of the Pevek model series, with a focus on advancing the core capabilities and performance of Cowork Agents (office productivity agents), achieving state-of-the-art (SOTA) performance among models of comparable scale across multiple benchmarks.面向 Search Agent 与 Cowork Agent 场景开展基础模型后训练研究,持续提升模型的通用能力与业务场景落地能力。参与 Pevek 系列模型研发,重点提升模型在 Cowork Agent(办公智能体)场景下的核心能力与复杂任务执行表现,在多项 Benchmark 上达到同等参数规模模型的 SOTA 水平。

2025.04 – 2026.01

Baidu百度 ↗

Research Intern · Xinghai Talent Program研究实习生 · 星海人才计划

Search LLM pre-training and reinforcement learning for query rewriting, with a focus on compressing chain-of-thought to reduce inference latency.参与搜索大模型预训练与查询改写模型的强化学习后训练,重点研究思维链压缩以降低推理延迟。

2024.01 – 2024.05
NIO · Shanghai蔚来 · 上海 ↗

Intern · BI Agent实习生 · BI Agent

Intent understanding, task routing, and LLM-based reasoning for the BI Agent framework.参与 BI Agent 框架开发,负责意图理解、任务路由与基于大语言模型的推理。

Education教育背景

05

M.S., Software Engineering软件工程硕士

Peking University北京大学

2023.09 – 2026.06

Advisor: Prof. Weiping Li导师:李伟平教授

B.Eng., Electronic Information Engineering电子信息工程工学学士

Wuhan University武汉大学

2019.09 – 2023.06